Your AI application is only as good as the QA behind it

LLM hallucinations, agentic side effects, RAG faithfulness failures, and voice agent errors only surface under specialist AI evaluation.

Contact Us Why Testiva

50+

Applications Tested

20+

Organizations Served

15+

Years Of Excellence

The gaps in health tech QA and how Testiva closes them

QA/Software Testing GAPS

  • AI performance is measured without clear metrics
  • Bias and fairness testing are skipped
  • Model and prompt updates lack regression testing
  • AI guardrails are never stress-tested
  • AI validation documentation is missing
  • AI testing is treated as a one-time activity

How Testiva Fills Them

  • Accuracy, safety, and consistency metrics before testing begins
  • Output tested across demographics and input variations
  • Automated AI regression testing for every release
  • Red teaming for harmful and unsafe outputs
  • Structured validation reports for compliance and audits
  • Continuous AI evaluation throughout the development

AI/LLM App testing types

Every testing type is designed for the dual challenge of Healthcare AI clinical accuracy requirements and AI evaluation methodology working together in the same engagement.

Functional & Output Validation Testing

API & Model Integration Testing

Adversarial & Red Team Testing

Hallucination Detection & Accuracy Testing

Latency & Scalability Testing

Bias & Fairness Testing

Prompt Regression Testing

Drift & Monitoring Testing

Reasoning & Decision Testing

Testing That Keeps Up with AI Regulations

We design testing strategies that help your AI systems meet evolving compliance requirements for safety, transparency, and reliability.

Tools We Use

Built for Regulated Environments

We design QA that aligns with compliance requirements in healthcare.

Purpose-Built Testing Tools for Multi-LLM Agents

Testiva developed a dedicated in-house platform for Multi-LLM Agent orchestration and coordination testing.

Purpose-Built Testing Tools for Medical RAG Agents

Testiva developed a dedicated in-house platform for Medical RAG Agent accuracy and safety testing.

Selected Work

We bring the industry’s best open-source and enterprise tools into your QA process.
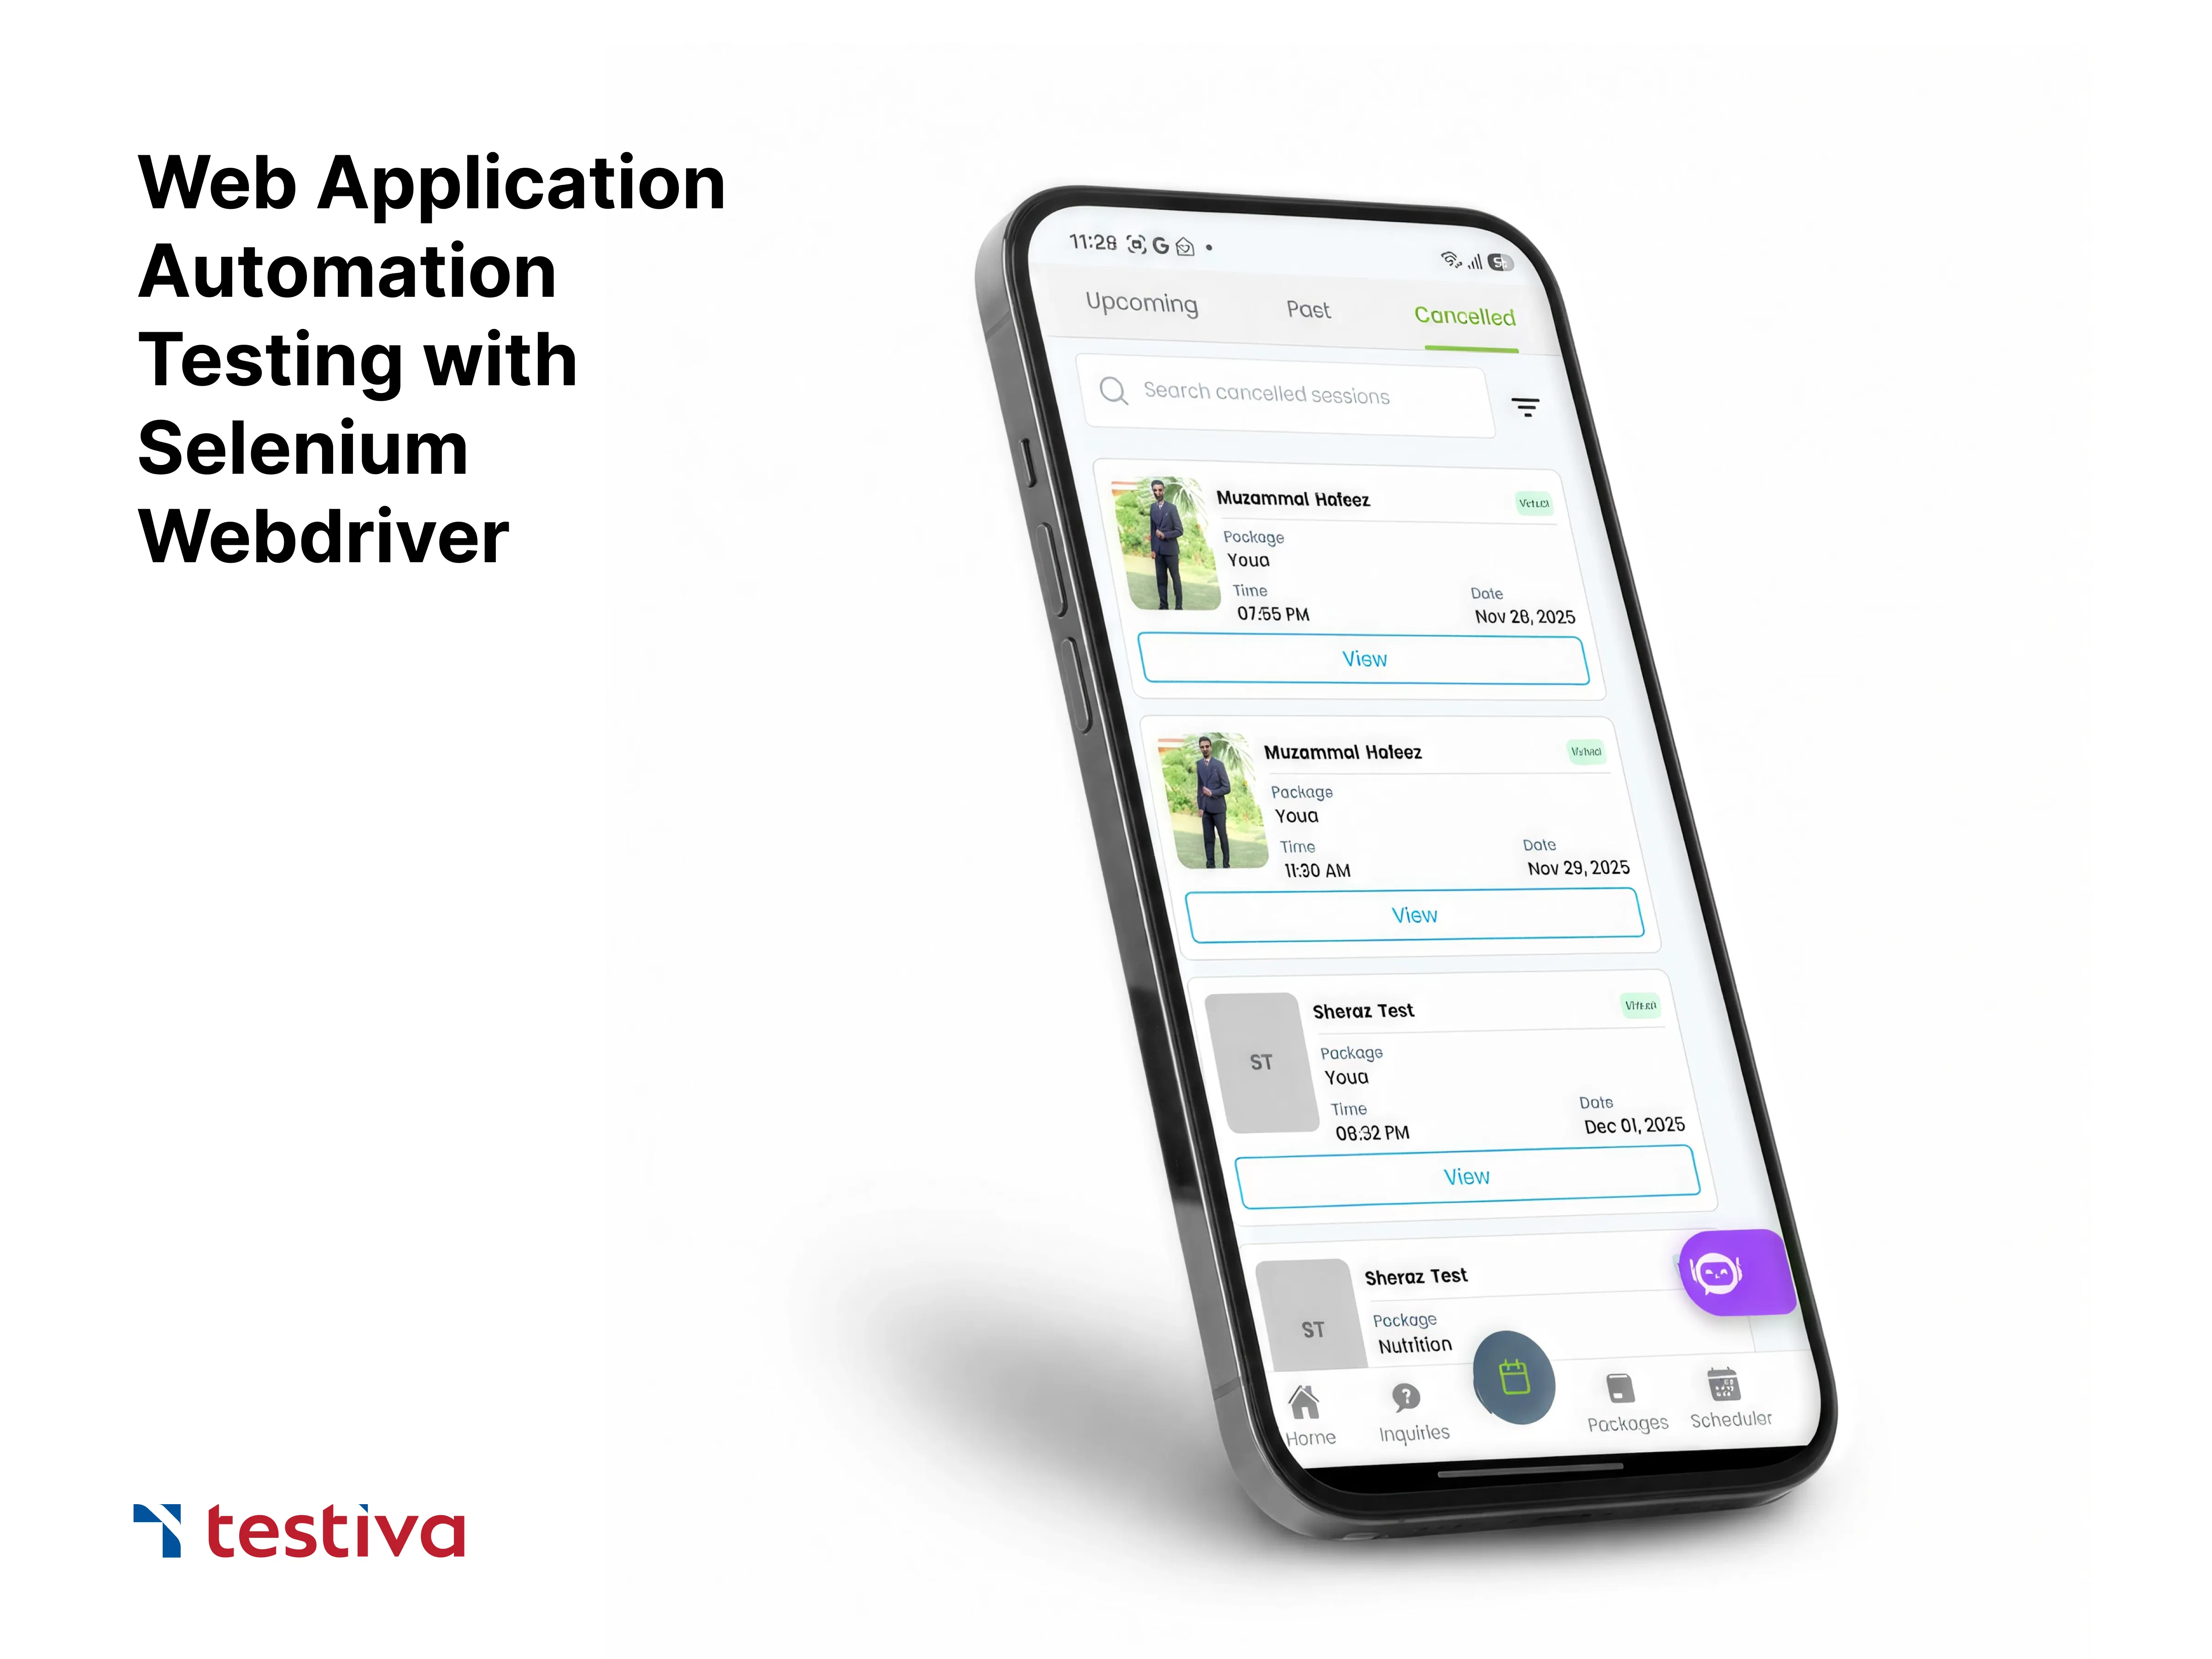
Holistic Wellcare Advisers (HWA)

Holistic Wellcare Advisors

Holistic Wellcare Advisors is a virtual coaching platform for scheduling and managing wellness sessions.

  • Mobile App Testing
  • Functional Testing
FreeAdCopy

FreeAdCopy

FreeAdCopy is an AI-powered platform that generates high-converting ad copy efficiently.
  • AI
  • Test Automation
  • API Testing
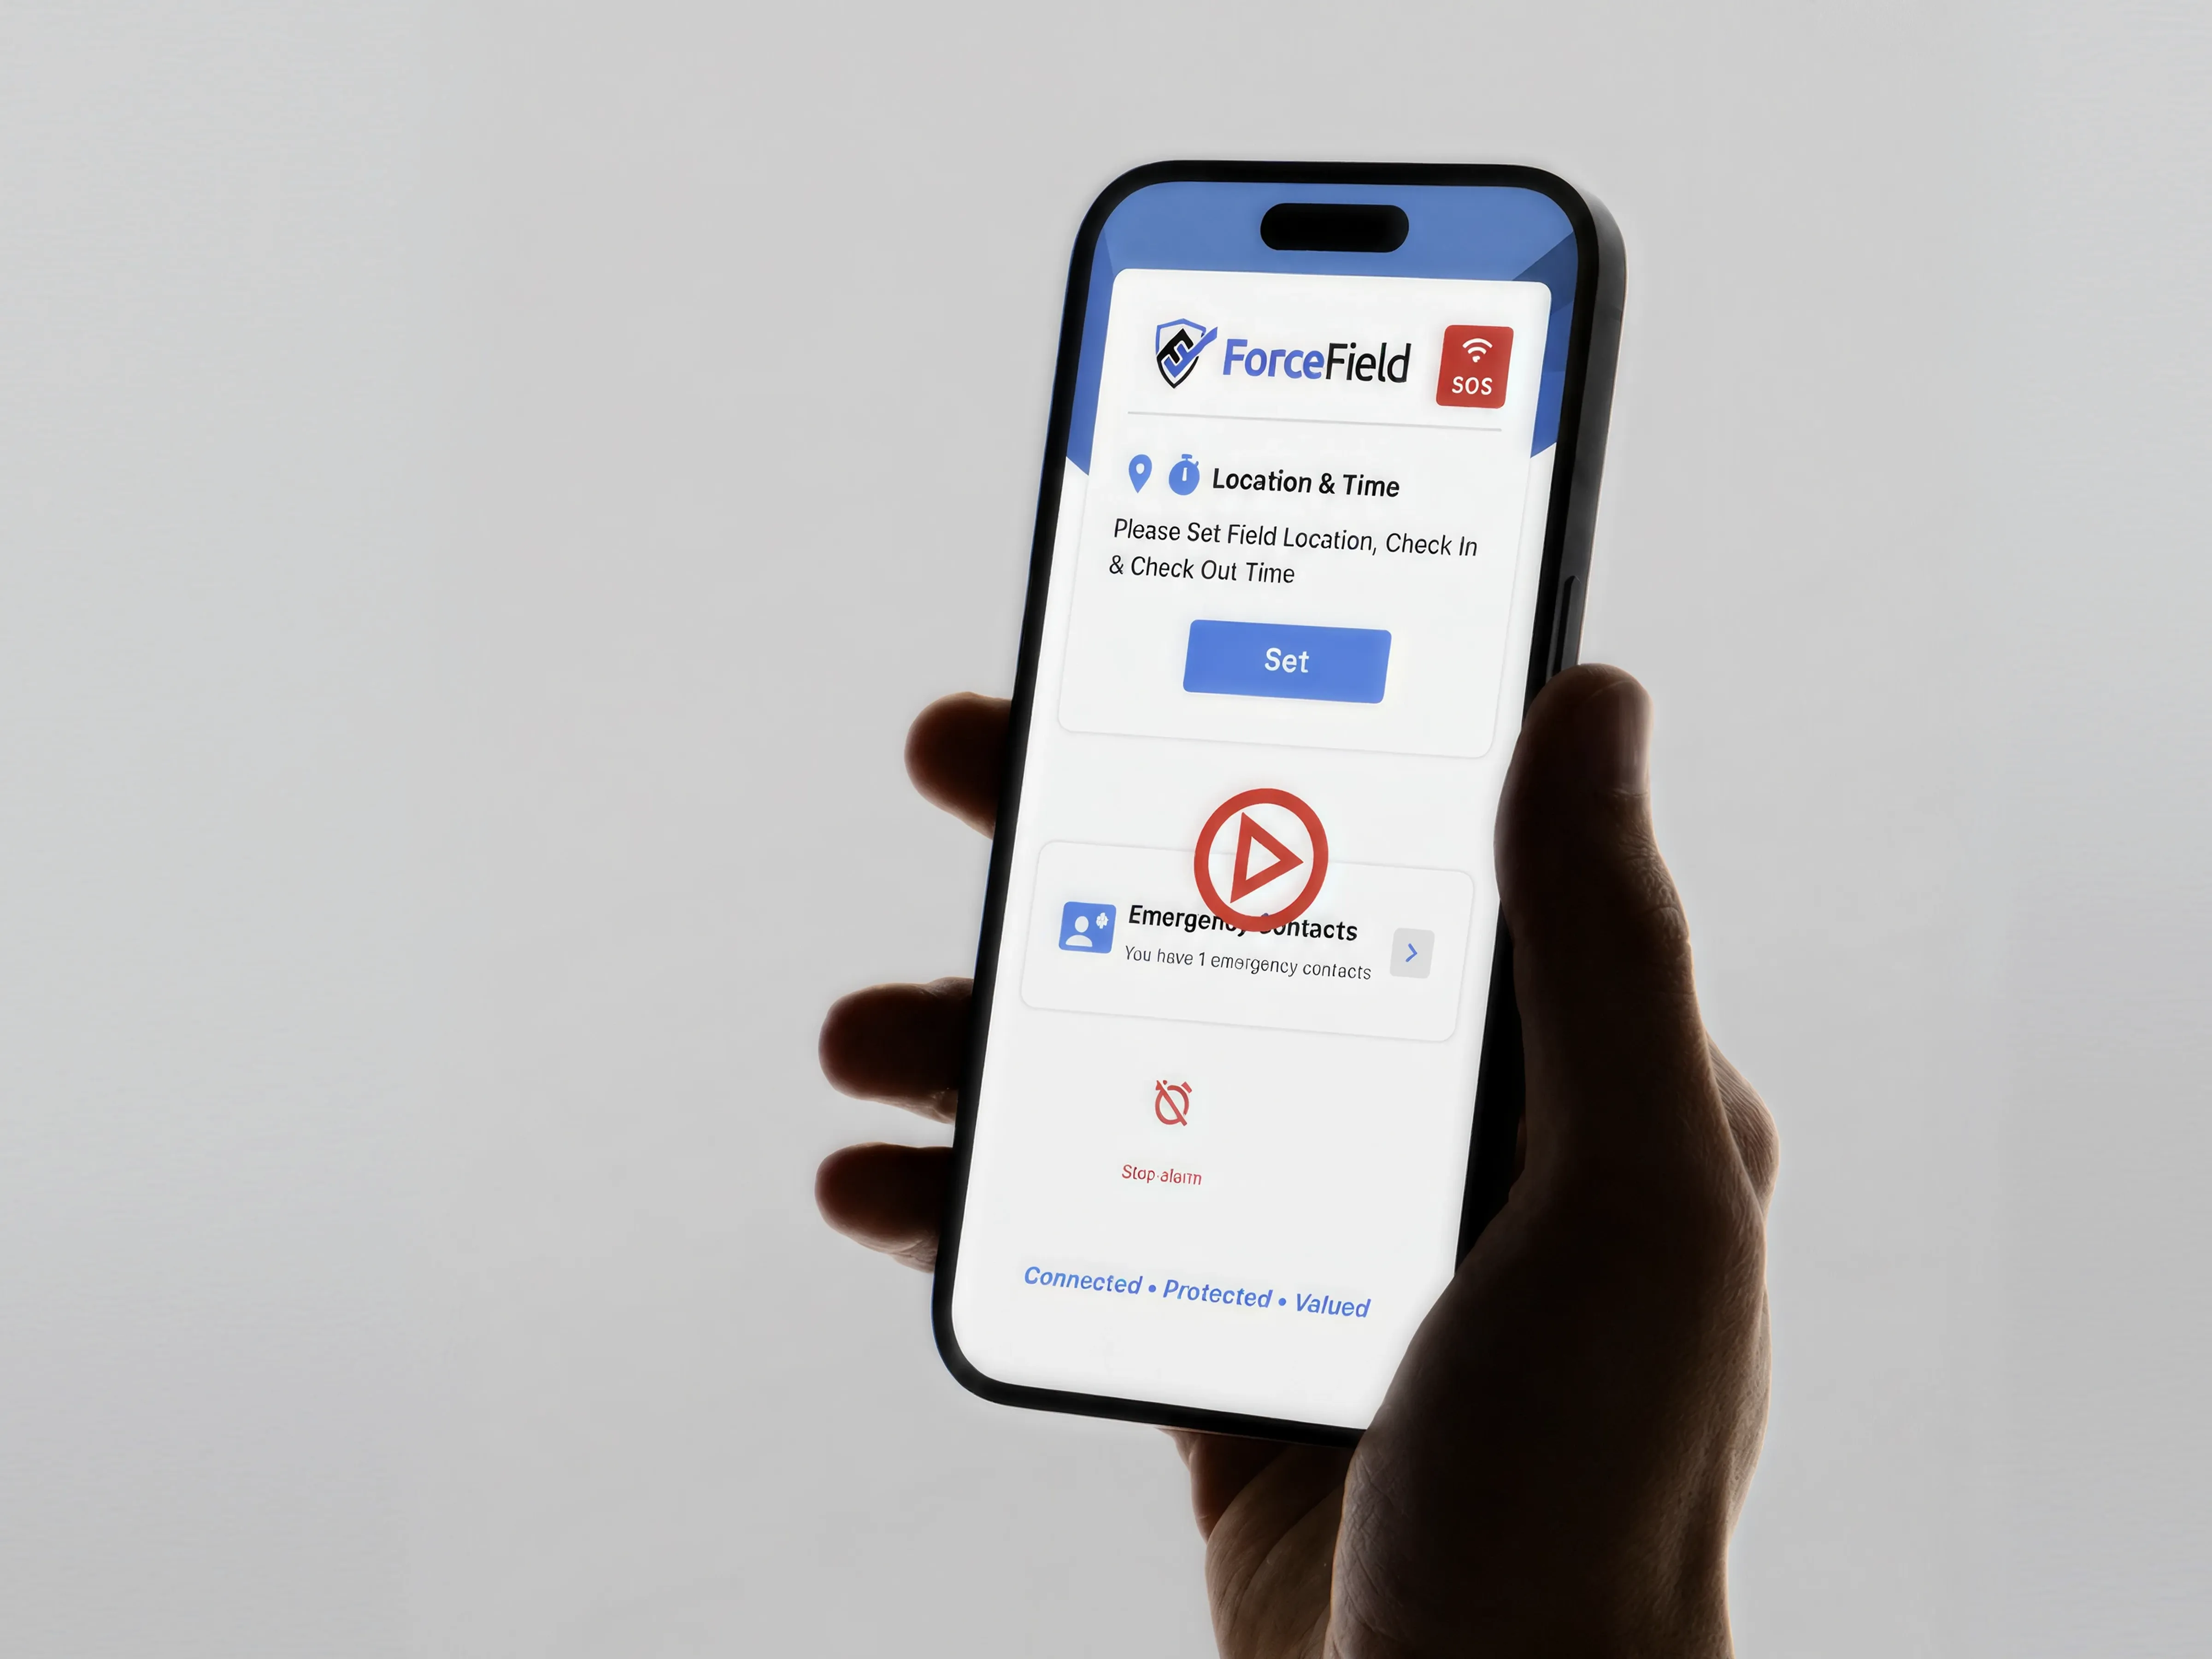
ForceField Protection

ForceField Protection

ForceField is a personal safety app offering SOS alerts and real-time check-in protection.

  • Mobile App Testing
  • Functional Testing
  • Security Testing
YOU(th) Health App

YOU(th) Health App

YOU(th) Health provides AI-driven health assessments using smartphones for quick check-ups.

  • Mobile App Testing
  • Test Cases
  • Jira

What People Say

Worked with Testiva for years in health tech; their thorough testing helped us deliver stable, high-quality software.Highly professional and easy to work with.

Testiva improved our QA process and integrated smoothly with our workflow and testing stack. They delivered reliable UI testing and valuable tech recommendations.

Client photo

Testiva is a great team to work with. I’ve hired them multiple times and recommended them to others, all impressed by their thorough work. Highly recommended for QA.

Client photo

Testiva team is highly skilled and extremely thorough. I trust them for accurate and timely delivery. They are a reliable resource for any project.

Client photo

Testiva team delivered outstanding quality with great professionalism. Communication was excellent and delivery met expectations. Highly recommended.

Client photo

Excellent team worked well with minimal supervision and did a great job. Their work helped us improve the robustness of the platform.

❮
❯

Common questions

Output quality, hallucination detection, prompt robustness, and safety none of which appear in standard functional test suites.
AI Agents, RAG Systems, Recommendation Systems, Voice Agents, Generative AI, and Computer Vision Applications.
We use statistically validated evaluation sets with human-calibrated rubrics, measuring quality distributions not single outputs.
Yes we test the full application layer including prompt design, output handling, and safety independent of the underlying model.
We run structured adversarial suites targeting prompt injection, jailbreaks, data extraction, and instruction override attempts.
Automated evaluation pipelines detecting output drift, hallucination rate changes, and safety regressions after every update.

Quality Isn’t Optional. Let’s Talk

From quick test coverage to full-scale QA teams, we plug in exactly where you need us.