


Latest Insights
A Guide to Testing Multi-Speaker AI Note-Taking Applications
- Aug 15, 2026
- Sajid M.
- Testing AI-Note Taking Applications
Introduction to Testing Multi-Speaker AI Note-Taking Applications
Most testing for an AI note-taking system assumes a simple setup: one doctor, one patient, talking one at a time. Real consultations don’t always work that way. A nurse knocks and says something briefly, a parent answers for their child, a sibling chimes in from the side of the room. Each of these adds a new speaker, and testing for it is a different problem than just testing a longer two-person conversation.
This blog covers what changes when you add more speakers, and what we found while testing these scenarios as part of Testiva’s evaluation of a real AI medical scribe. It also highlights why healthcare AI testing must include realistic multi-speaker scenarios to evaluate system performance accurately. It also explains why multi-speaker AI note-taking testing is essential for evaluating real-world clinical conversations.
Why Multi-Speaker Conversations Are Challenging for AI Note-Taking Applications
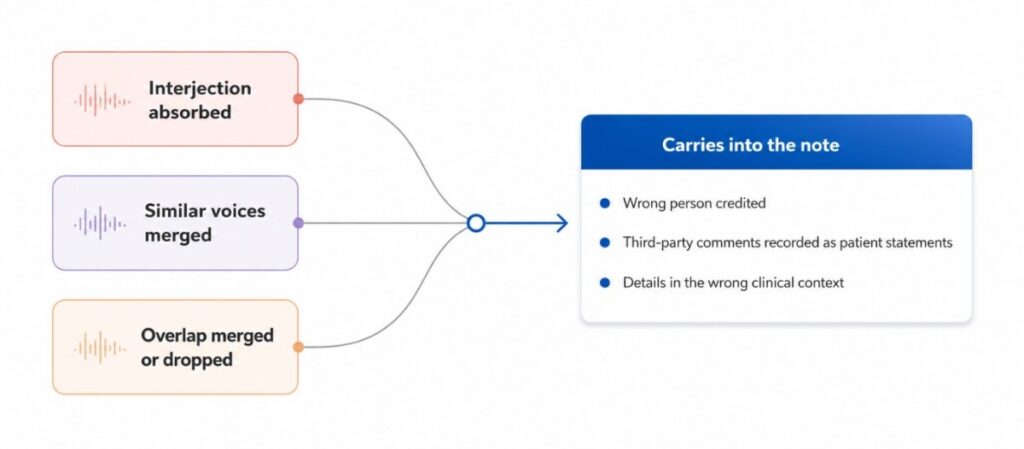
Adding even one extra speaker makes speaker attribution significantly more difficult. A short interruption may be absorbed into the speaker immediately before or after it instead of being recognized as a separate person. Similar-sounding voices, such as a parent and child recorded in the same room, can be mistaken for the same speaker, while overlapping speech can cause utterances to be merged together or dropped entirely.
These errors begin during transcription, but they rarely end there. Because AI note-taking applications generate clinical documentation directly from the transcript, speaker attribution mistakes can carry into the final note. Information may be assigned to the wrong person, third-party comments can be recorded as patient statements, and details can appear in the wrong clinical context. What starts as a transcription error can ultimately become a documentation error, making accurate speaker attribution an essential part of evaluating AI note-taking systems.
What Is a Multi-Speaker Scenario in AI Note-Taking Applications?
Multi-speaker testing isn’t a single scenario. Different conversation patterns introduce different challenges, so testing one doesn’t necessarily tell you how the system will perform in another.
Some of the most common scenarios include:
- Brief third-party interruptions: A nurse or another clinician briefly joins the conversation before leaving.
- An accompanying person: A parent, sibling, spouse, or caregiver participates throughout the consultation alongside the patient.
- Overlapping speech: Two people speak at the same time, whether in a two-person or multi-speaker conversation.
Each of these changes the structure of the conversation and tests a different part of the AI note-taking pipeline.
How to Generate Multi-Speaker Test Data for AI Note-Taking Applications
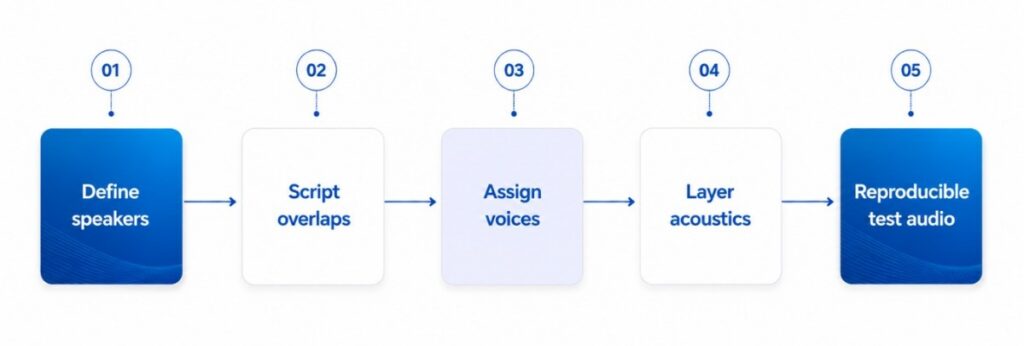
For our testing, the multi-speaker scenarios came from the script generation step itself. Rather than recording the audio first and adding overlapping speech on top of it afterward, we asked for a specific number of speakers and roles (for example, doctor, patient, and an accompanying sibling) and let the script generation naturally write interruptions and overlapping turns directly into the dialogue, the same way they’d occur in a real conversation.
As part of Testiva’s testing framework, this allows the same scenario to be reproduced consistently across different recording conditions, making it easier to isolate whether failures originate from the audio, transcription, or note-generation stages.
Each speaker was then given a distinct synthetic voice. Background acoustic conditions, like room noise or mic placement, were layered on separately afterward, but the overlapping and interrupting speech itself came from how the conversation was written, not from an audio effect applied on top of a clean recording.
Common Multi-Speaker Challenges in AI Note-Taking Applications
The examples below were observed during Testiva’s evaluation of a live AI medical scribe and illustrate how multi-speaker conversations can reduce diarisation accuracy and affect downstream note generation.
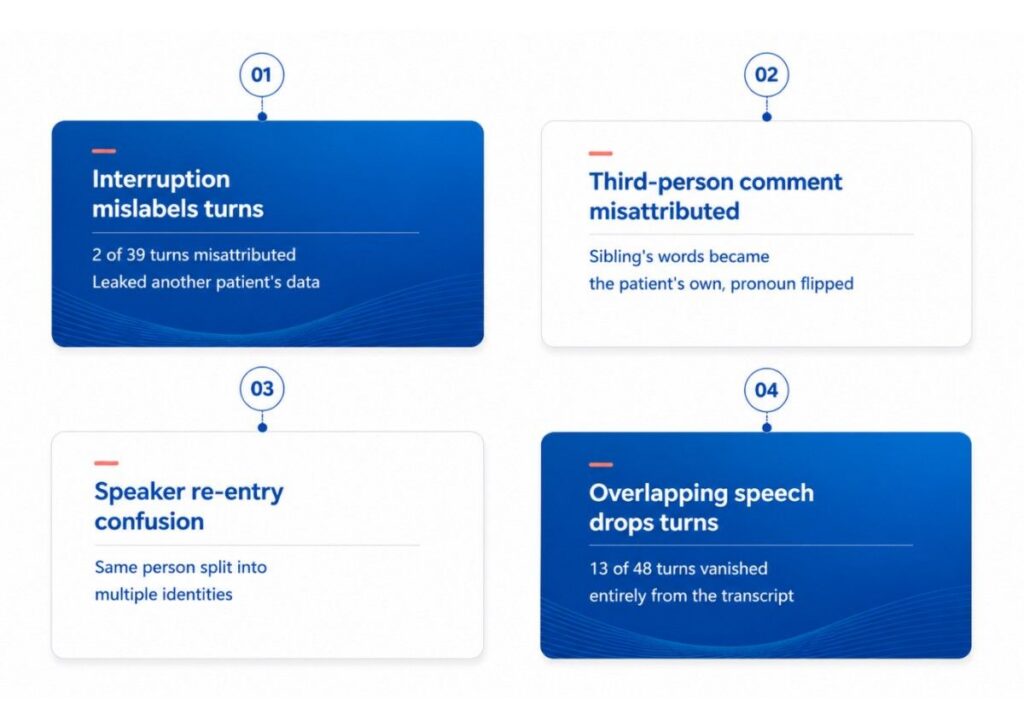
A brief interruption can mislabel exactly the wrong turns.
In one consultation with a nurse stepping in briefly, two of the nurse’s lines after the interruption were mislabeled as the patient’s own speech, even though every other turn in the conversation, including the doctor’s, was attributed correctly. Out of 39 total turns, only those 2 were wrong, a small number on paper, but they happened to be the exact moment most likely to matter. In the same test case, the nurse’s brief comment mentioned a completely different patient’s lab result, and that detail ended up written into the current patient’s clinical note.
A third person’s comment can come out sounding like the patient’s own words.
In a consultation with an accompanying sibling, the sibling’s comments about the patient, spoken in the third person, were misattributed to the patient’s own speaker label more than once. In one case, this went further than just a wrong label: a doctor’s line referencing the sibling’s comment, “you mentioned some heartburn,” had actually been “he mentioned some heartburn” in the original conversation, with the pronoun itself flipped from third person to second person along the way.
The speaker re-entry confusion after silence.
In consultations where one speaker leaves the conversation for a while and then returns (for example, a parent stepping out and coming back later), the system sometimes treats them as a new speaker instead of the same one. When they re-enter, their new statements get assigned a different speaker label. This can split a single person’s contributions into multiple identities in the transcript, which then carries over into the final note and makes the clinical history look like it involves more people than actually participated.
Overlapping speech can cause turns to vanish rather than just blur together.
In a consultation with frequent overlapping speech between doctor and patient, 13 of 48 total turns were missing entirely from the transcript. Short responses from the patient were the most likely to disappear, with their words instead showing up scattered into nearby segments rather than attributed to anyone.
Conclusion
Multi-speaker AI note-taking testing helps uncover challenges that aren’t present in standard two-person consultations. A strong QA framework helps identify speaker attribution errors, overlapping speech issues, and information leakage before they affect clinical documentation, improving both note accuracy and patient safety.
At Testiva, we apply these best practices through realistic multi-speaker test generation, layer-by-layer evaluation, and comprehensive validation of both transcripts and generated notes. This structured approach supports reliable healthcare AI testing by helping teams identify speaker attribution failures before they affect clinical documentation.
Ready to evaluate your AI note-taking application in complex multi-speaker scenarios? Contact Testiva today for a demo of our testing framework and learn how structured healthcare AI testing can improve transcription accuracy and strengthen trust in your AI-generated clinical documentation.